The retrieval part of the PACOD platform is pacod-kb. It ingests files and web pages, converts them to canonical Markdown, indexes them for hybrid semantic and keyword search and keeps every version. A model that asks it a question gets passages it can cite, fenced as data. This post follows a document through it, explains what its search scores do and do not say, and shows how to run it.
Why it exists
Most of the work in retrieval-augmented generation happens before a model reads a word: getting documents in, keeping them clean, finding the right passage and telling the model where it came from. That work is the same whatever the model or the application, so pacod-kb does it as a service of its own, with an HTTP API, a web UI and a CLI.
Three demands shaped it. Answers must be citable, so every passage carries its heading path and byte offsets into a stable Markdown body. Sources change, so nothing is overwritten: a new version supersedes the old one, which stays searchable by date. And ingested text ends up in a model's prompt.
Whoever can get a page into a knowledge base can try to give orders to the model that reads it. pacod-kb treats every ingested text as untrusted input: scanned before it is stored, fenced as data when it is returned.
From a document to chunks
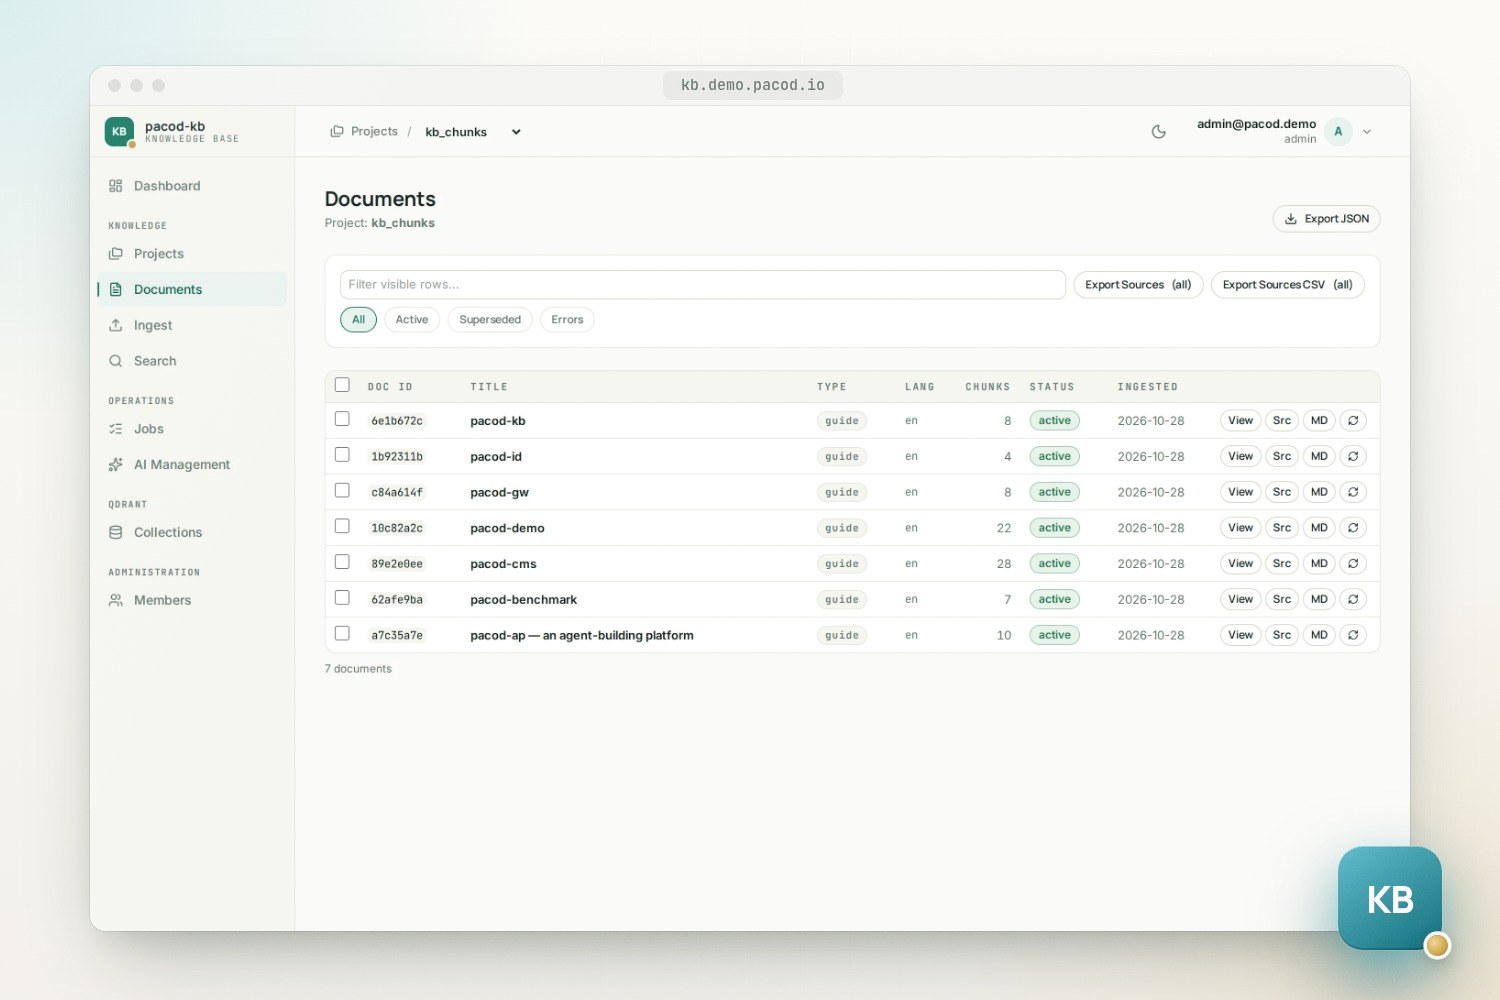
A document takes the same path whether it was uploaded, dropped into a folder, fetched from a URL or re-fetched from a watched web page. Its id is the SHA-256 of its bytes, so the same file is never ingested twice. Parsers turn PDF (through docling, with optional OCR), DOCX, HTML, Markdown, text and JSON into Markdown with YAML front matter, and a language check accepts eight languages: English, German, Bulgarian, Russian, Serbian, Macedonian, Croatian and Slovenian.
Then comes the scan, and its place in the order matters. It reads the deterministic parse before any model sees the text: a converter could follow instructions hidden in a document, and converting would strip the zero-width characters and hidden markup the scan looks for. It has three verdicts:
- Block fails the ingest and stores nothing. One high-severity finding is enough: an unambiguous instruction override such as "ignore previous instructions" (in English, German, Russian or Bulgarian), a bidirectional-override character, or an instruction hidden in base64. So is a high threat score.
- Quarantine keeps the document for review, never sends it to a model and never indexes it.
- Clean lets it through.
Spam alone never blocks, and neither should ordinary technical prose: phrases such as "enable developer mode" count as low severity, so a single one cannot block a document.
Only then may an LLM tidy the Markdown, through pacod-gw, which holds the provider
keys and prices the call. The pass is optional and cannot lose a document: a cut-off, refused or
empty answer keeps the deterministic parse, and a converted body is scanned a second time. A noise
filter removes page numbers, running headers and cookie notices, and headings are recognised in
legal texts, papers and articles. Last, heading-aware chunks of up to 500 tokens are embedded with
BGE-M3, each with a breadcrumb such as [pacod-demo > How it is put together] in front, and
written to the project's Qdrant collection and keyword index.
Search, measured
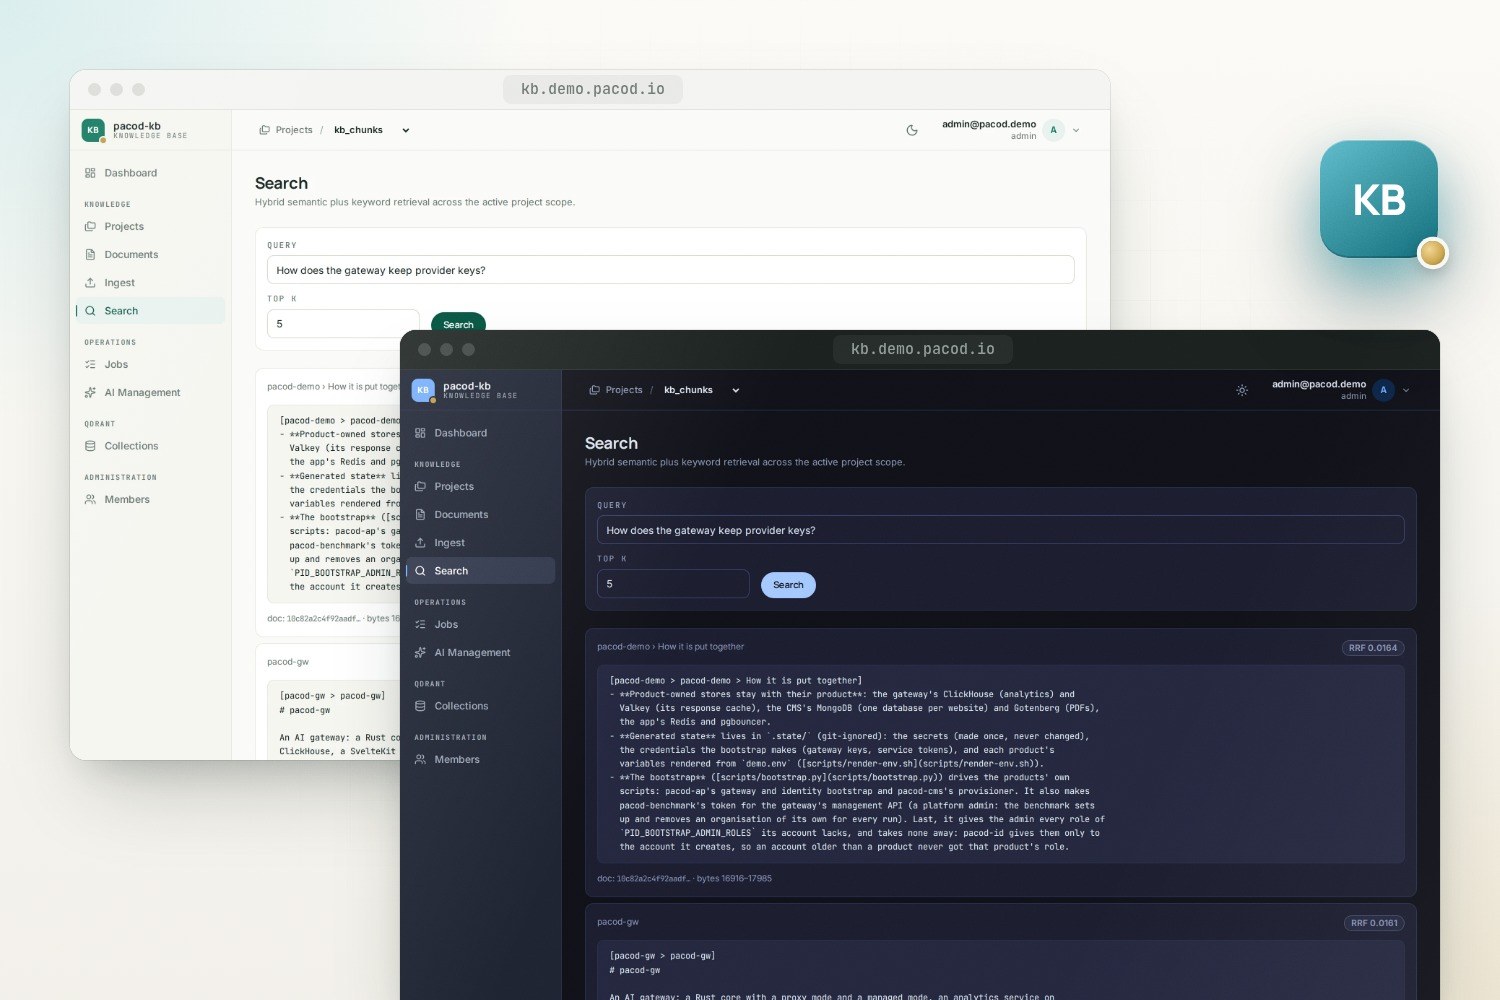
A question runs against both indexes at once: BGE-M3 vectors in Qdrant, and keywords in SQLite FTS5 or PostgreSQL. The two rankings are fused with reciprocal rank fusion: each list adds 1/(60 + rank) for every passage it found. Date filters apply inside both searches, so old versions cannot crowd out the current one.
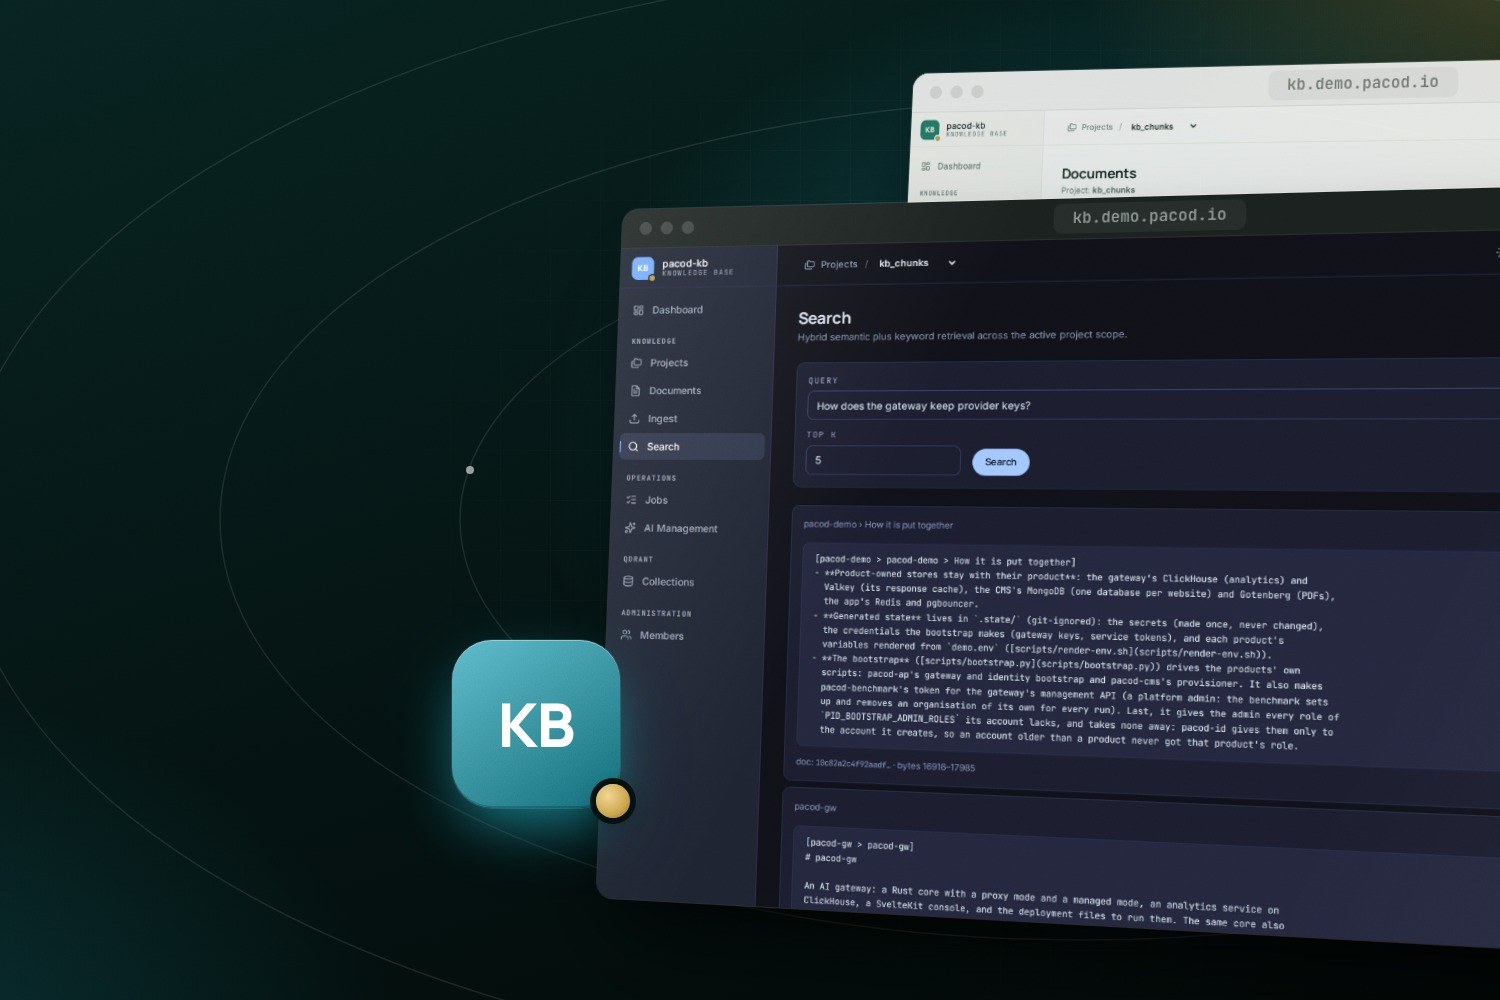
The scores say more than they seem to. Asked "How does the gateway keep provider keys?", a knowledge base holding the seven PACOD READMEs puts a passage from pacod-demo first, at 0.0164, and one from pacod-gw second, at 0.0161. Those are 1/61 and 1/62: first and second place in the vector list, and nothing from the keywords. By default the keyword half requires every word of the query to match, which a natural question rarely does. The project's own evaluation saw the same: 0.0164 at the top for every unanswerable query and for most correct hits. An RRF score orders one list; it does not say whether a passage answers.
That evaluation is a harness in the repository: 14 documents in six languages (GDPR, the Law Enforcement Directive, four constitutions, Wikipedia articles) and 92 hand-written queries, among them paraphrases, exact terms, cross-lingual, native-language and unanswerable ones. A result counts when it comes from the labelled section, so the labels survive changes to the chunker. On a development machine's CPU, which the docs stress gives no production numbers:
- The right section is among the fused candidates for every answerable query, and in the top five for 98.7 % of them, at about 50 ms. R@1 is 0.83: the headroom is in the order.
- A cross-encoder reranker,
BAAI/bge-reranker-v2-m3, lifts R@1 to 0.91, at about 2 s per query. Its 0–1 score does separate answers from non-answers:min_score0.1 drops 14 of 15 unanswerable queries and 2 of 70 correct top answers. - A search during a heavy ingest used to wait about 24 s behind a whole embedding batch. Queries now go ahead of ingest work and wait for one small batch at most: 0.41 s (p50) with jobs run one after another, as the pipeline runs them.
The reranker is still off by default. Its gain fell just short of the bar on the held-out half of the queries, and its latency has to be confirmed on the production CPU. A smarter keyword half, with stopwords dropped and inflections stripped, helped native-language and exact-term queries but hurt cross-lingual ones and lost on the held-out half, so it stays an option too.
Versions and the contract
A new version, or a watched page that has changed, marks the old one with valid_until, in the
front matter, the manifest, the keyword index and the vectors at once. If a watched page reverts,
the earlier version is reinstated. Searches return current passages by default; as_of returns
what was valid on a given day, and include_historical returns everything. A consumer posts its
question to the pipeline's /query:
{"query": "maximum fine for a data breach", "top_k": 5, "as_of": "2025-12-30"}
Each result carries a stable chunk_id that encodes the heading structure, the document's
source_id, a heading_path such as ["Chapter 1", "§ 5"], byte offsets into the stored
Markdown, valid_until, and the text, wrapped in a fence that tells the model to treat it as data,
not instructions. The response also says which score ordered it: "score_kind": "rrf", or
"rerank" when the reranker did. These fields are documented as a contract, so a consumer can
attribute a passage with " > ".join(heading_path) and fetch the exact bytes behind it. The
offsets are UTF-8 bytes, not characters, which matters for Cyrillic text.
Running it
kb's own stack needs Docker and checkouts of pacod-id and pacod-gw beside it:
make setup
make up
open http://localhost:8080/kb
make setup writes .env with generated secrets and prints none of them. make up starts kb with
its own copies of the shared pieces: Qdrant, PostgreSQL, pacod-id for sign-in, a
mail catcher, and pacod-gw-lite in front of mock providers, so nothing leaves the machine. Sign in
with the admin account from .env; the viewer, editor and admin roles are granted at pacod-id. The
pipeline, which parses untrusted documents and fetches URLs, never receives pacod-id's secrets,
and the UI never sees the gateway key. Because the mock echoes the prompt, the development stack
leaves conversion off; with no gateway configured at all, AI is off and nothing else breaks.
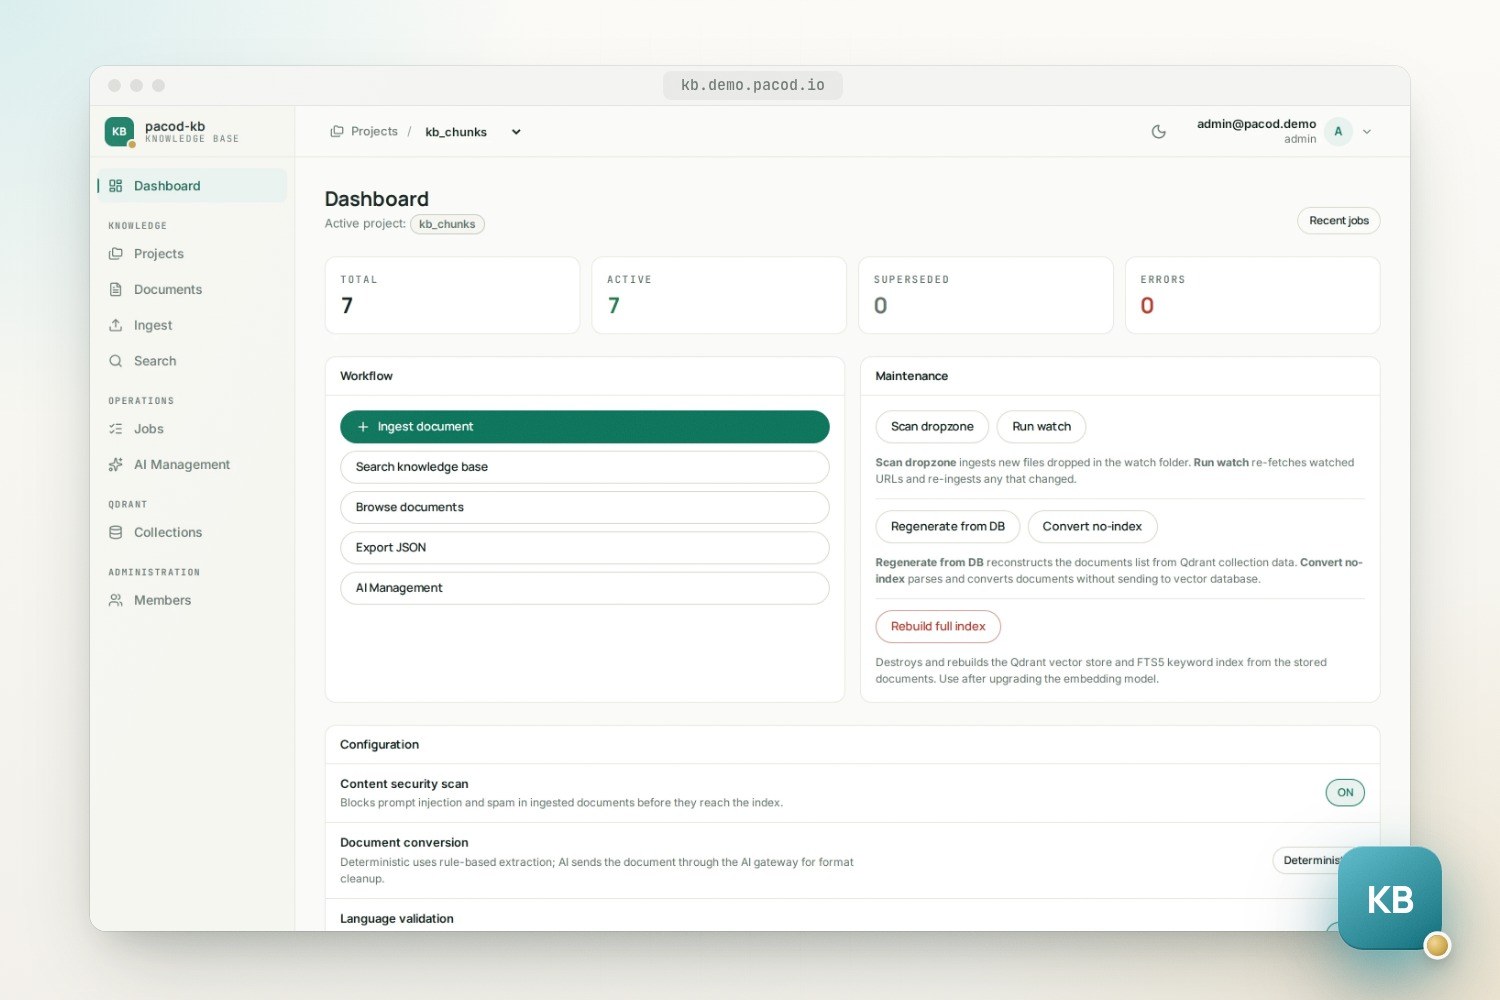
In the full stack, pacod-demo runs kb with the other products: its collections on the shared Qdrant, its database on the shared PostgreSQL, and its embeddings from pacod-ap's embeddings service, which gives the same vectors and saves the pipeline about 2 GB of memory.
The product page has the architecture, the security model and the settings. The code, the metadata contract and the full evaluation are in the repository, and the knowledge base runs in the live demo.